How Jacqueline Cheong and Robin Tang Are Giving AI Companies Real-Time Data Infrastructure
Artificial intelligence is only as useful as the information it can access. A model may be powerful, but its responses can become unreliable when it depends on old customer records, delayed transactions, outdated inventory, or incomplete product data.
This creates a growing challenge for companies building AI tools. Companies may store their daily operational data in databases such as PostgreSQL, MySQL, or MongoDB, while using a separate data warehouse for analytics and AI. Moving information between these systems can take hours and require significant engineering work.
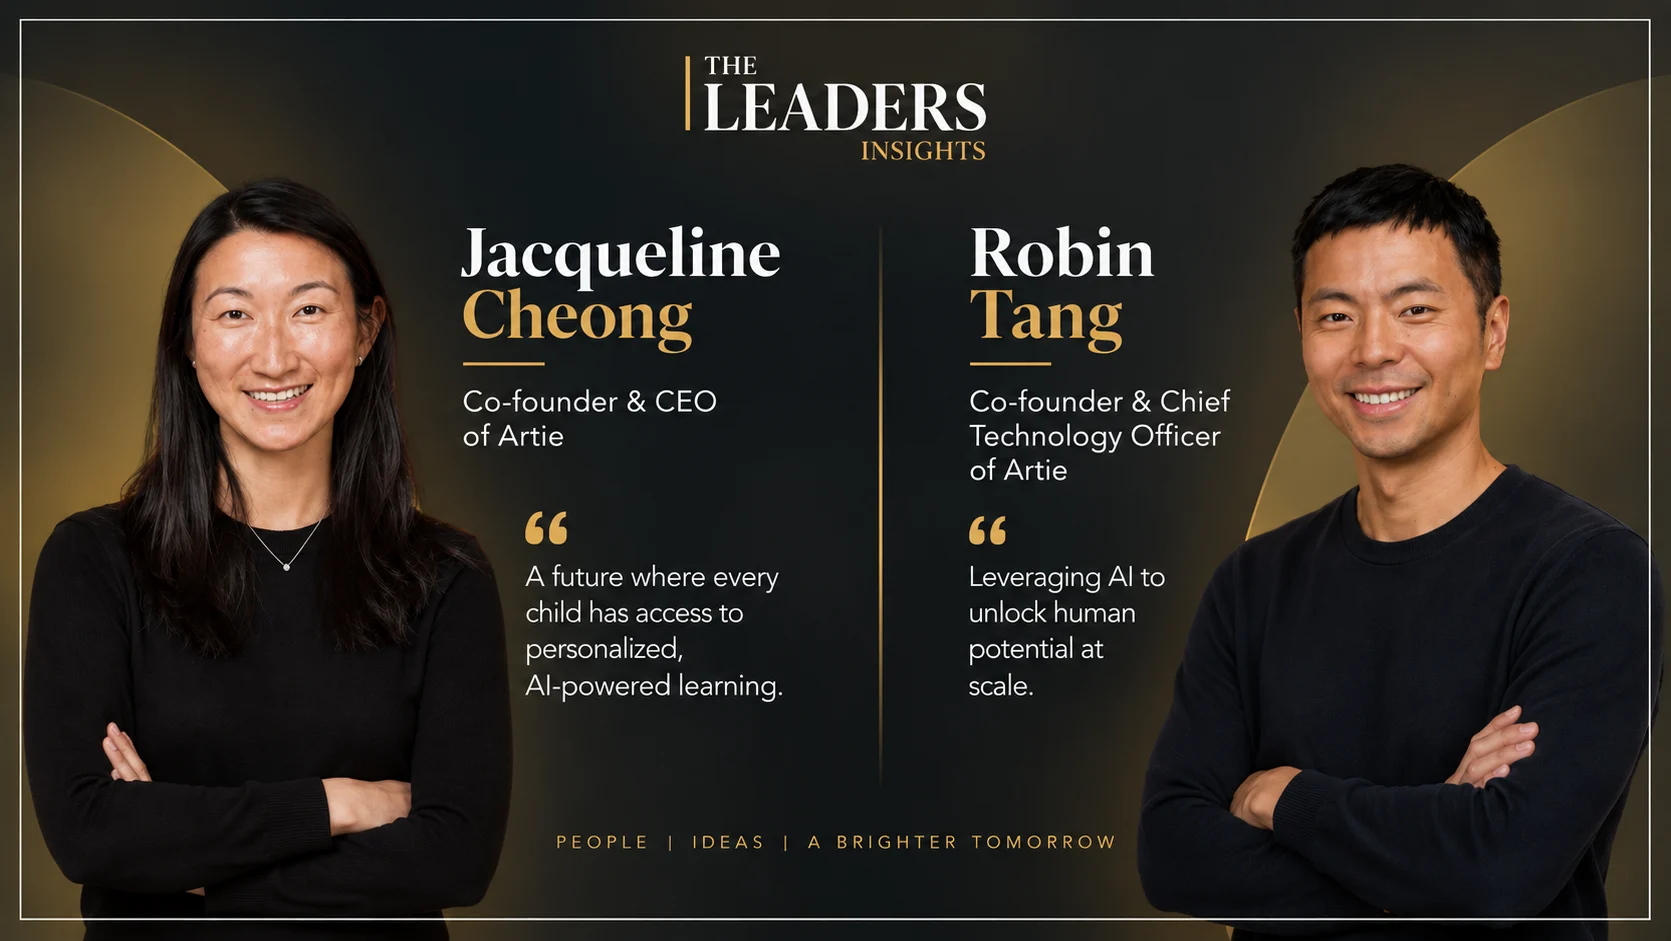
Jacqueline Cheong and Robin Tang founded Artie to solve this problem. The San Francisco-based company provides real-time data replication software that moves updated information from operational databases into cloud data warehouses.
Cheong leads Artie as co-founder and CEO, while Tang serves as co-founder and chief technology officer. Together, they are building the infrastructure that allows AI applications, analytics platforms, and business teams to work with fresher data.
Their company shows how a focused infrastructure startup can become valuable by solving a technical problem that affects the entire organization.
The Problem With Delayed Business Data
Most businesses store daily operational information inside production databases. These systems may contain customer accounts, orders, transactions, support requests, product activity, and other records required to run the company.
Data teams often copy this information into a warehouse such as Snowflake, BigQuery, Redshift, or Databricks. The warehouse can then support reporting, analysis, machine learning, and other business functions.
Traditional data pipelines may move information in scheduled groups. Some run every few hours, while others update overnight. This method can work for monthly reports, but it is less useful when a company needs to respond immediately.
Consider an AI support assistant using yesterday’s customer data. The system may therefore rely on outdated data and miss recent activity, including payments, order cancellations, account updates, or customer communications. A recommendation system may continue showing a product that is no longer available. A fraud tool could miss a new transaction until the next data update.
What happens when an AI system works with incomplete information? It may produce an answer that appears confident but does not reflect the customer’s current situation.
Real-time replication is designed to reduce this delay.
Robin Tang’s Experience With Data Pipelines
Tang developed the idea for Artie after working with large and complex data systems.
According to Artie, Tang built his first large-scale data ingestion pipeline in 2016 while working at a San Francisco startup. The system processed billions of events each day, teaching him how difficult it can be to maintain reliable performance without creating high costs.
After the startup was acquired by Zendesk, he helped build the foundation for its customer relationship management product. That work involved Change Data Capture and Apache Kafka, two technologies commonly used to move information between systems.
Later, while working at a real estate technology company, Tang encountered further delays and data-processing errors. These problems increased operating costs and limited the company’s ability to build new products.
In 2022, he began developing his own solution. The initial version showed promise, but it also revealed the full complexity of database replication. A production-ready service must handle changing database structures, different data types, large backfills, interruptions, and recovery without losing or duplicating information.
Tang understood the technical problem. Turning the solution into a business required a leader who could shape its market strategy.
Jacqueline Cheong’s Role in Building Artie
Cheong joined Tang to develop the company, lead its commercial direction, and bring the product to market. The two founders combined Tang’s background in distributed systems with Cheong’s focus on company building, customer development, and growth.
Artie joined Y Combinator’s Summer 2023 program. TechCrunch reported that the company raised a $3.3 million seed round led by Exponent Founders Capital, with participation from General Catalyst, Y Combinator, and angel investors.
Artie later raised a $12 million Series A led by Standard Capital, according to the company. Its development from an internal technical idea to a funded infrastructure business offers a useful lesson for founders: important opportunities often appear inside work that engineering teams have accepted as difficult but unavoidable.
Cheong and Tang did not create another AI model. They focused on the infrastructure required to make AI products more useful.
How Artie Moves Data in Real Time
Artie uses a process called Change Data Capture, or CDC. Instead of repeatedly copying an entire database, CDC identifies individual changes as they occur.
If a customer updates an address, an order changes status, or a payment is recorded, the platform captures that event and sends the updated information to the selected destination.
Artie combines CDC with stream processing. This allows data to move continuously rather than waiting for the next scheduled batch.
The basic process includes three stages:
- – The company connects to a source database
- – It selects the tables and fields it wants to replicate
- – Artie streams the changes to the chosen data warehouse
The platform supports sources that include PostgreSQL, MySQL, MongoDB, DynamoDB, CockroachDB, DocumentDB, and Amazon Keyspaces. Available destinations include Snowflake, BigQuery, Redshift, Databricks, PostgreSQL, Amazon S3, Google Cloud Storage, and ClickHouse.
Artie states that its platform can deliver changes with sub-minute latency. The exact performance will depend on the customer’s workload, system design, and configuration.
Why AI Companies Need Fresh Information
Modern AI applications increasingly need access to live business data. A general language model may understand language, but it does not automatically know what happened inside a company several minutes ago.
An AI sales assistant needs current information about leads and customer activity. A financial tool may need the latest transaction status. A healthcare application must work with accurate records while following strict privacy rules. An operations platform may need to know whether an order has shipped or a product remains available.
Real-time infrastructure helps close the gap between a company’s operational systems and its AI tools. It does not make the model perfect, but it gives the application access to more recent facts.
This distinction is important for executives. Many AI projects focus heavily on selecting a model while giving less attention to the data pipeline behind it.
For companies building AI agents, data speed also affects action. An agent that only writes summaries may tolerate some delay. A system that changes an account, responds to a customer, or starts a business process needs a much more reliable view of current events.
Reducing the Engineering Burden
Companies can build real-time data infrastructure internally, but doing so requires experienced engineers and ongoing maintenance.
An internal team may need to deploy Kafka, configure database connectors, manage processing services, monitor replication delays, support new data types, and repair pipelines after failures. Schema changes create another challenge. When developers add or rename fields in a production database, the data pipeline must adjust without breaking downstream systems.
Y Combinator describes Artie as automating the data ingestion process, including change capture, merging, backfills, and monitoring. This allows customers to use a managed platform rather than assigning a large internal team to build the same capability.
For CEOs, this is not only a technology decision. It is also a question of focus.
Should a software company spend years building its own data infrastructure, or should its engineers focus on features that give the business a competitive advantage? The answer depends on the company’s scale, security needs, technical expertise, and product strategy.
Artie helps organizations access real-time data without having to build and manage the supporting infrastructure themselves.
Making Data Pipelines Easier to Monitor
Speed is only useful when the information arrives correctly. If records are missing, duplicated, or delayed without warning, business teams may make decisions using unreliable data.
Artie includes monitoring features that help engineering teams see how their pipelines are performing. The platform also supports schema changes, backfills, and failure recovery.
Observability is especially important for AI systems because a data problem may first appear as an incorrect model response. Without clear monitoring, a team may blame the AI model when the real issue is a delayed or broken pipeline.
A reliable platform should help engineers answer practical questions:
- – Is the source database connected?
- – How far behind is the destination?
- – Did a database change affect the pipeline?
- – Are all records arriving correctly?
- – Can the system recover without copying everything again?
Clear answers reduce the time spent investigating errors and help teams restore service faster.
Supporting Established Technology Companies
Artie’s customers provide examples of how real-time replication can support broader business goals.
The company says Substack uses Artie to move data from PostgreSQL and DynamoDB into Snowflake. According to an Artie customer case study, the platform transfers about 1 billion rows per month for Substack, with an average latency of 10-15 seconds.
Substack’s data team reported that fresher information helped it run experiments and make decisions faster. Artie reported these figures based on one customer’s experience. Results may differ for other businesses.
Artie also works with ClickUp. ClickUp’s data platform must combine information from a growing number of smaller PostgreSQL databases before sending it to Snowflake. Its team needed a solution that could handle this environment without frequent full reloads or extensive manual recovery.
According to ClickUp’s account published by Artie, the platform reduced recovery time and enabled the company to support reporting, experiments, and newer AI-related projects with more current information.
These examples show that real-time data can support many teams at once. Engineering builds the pipeline, but the benefits may reach product development, marketing, finance, customer service, and senior leadership.
Protecting Sensitive Information
Moving production data creates serious security responsibilities. A replication provider may handle customer details, financial information, internal records, or other sensitive data while transferring it between systems.
Artie states that it does not store customers’ replicated data. The company says it reads changes from the source log and streams them to the chosen destination.
Business leaders should still complete their own technical, legal, and security reviews before selecting any infrastructure provider. Important areas include access controls, encryption, audit records, incident response, data location, system availability, and support during failures.
AI systems do not reduce the need for data governance. They make it more important because information may be used automatically across a growing number of tools.
Leadership Lessons From Cheong and Tang
Artie offers several lessons for CEOs, founders, and managing directors.
First, the founders selected a problem they understood through experience. Tang had built and maintained complex pipelines before creating the product. That knowledge helped the company focus on real operational difficulties rather than a fashionable technology trend.
Second, Cheong and Tang built complementary leadership roles. Product and engineering sit with Tang, while Cheong leads the business and market strategy. Clear ownership can help a young company move quickly without losing direction.
Third, Artie supports the AI market without competing to build the largest model. AI infrastructure companies can create value by helping businesses manage data, strengthen security, monitor systems, and maintain reliable performance.
Finally, the company addresses a need that grows with its customers. As an organization adds more users, products, databases, and AI applications, dependable data movement becomes increasingly important.
Building the Data Layer Behind AI
AI companies are under pressure to create faster, smarter, and more personalized products. Reaching that goal requires more than an advanced model. It requires reliable access to current business information.
Jacqueline Cheong and Robin Tang are building that connection through Artie. Their platform moves database changes into cloud warehouses so that analytics tools, employees, and AI applications can work with fresher data.
The company’s larger message is straightforward: real-time intelligence begins with real-time infrastructure.
For business leaders, this should influence how AI investments are evaluated. Models may attract the most attention, but the underlying data determines whether an application can respond accurately to what is happening now.
Cheong and Tang have focused on that less visible layer. By making database replication faster and easier to manage, they are helping companies build AI products on a stronger foundation.